← Back to Workflows
Workflow
September 18, 2026

How to Turn 1000+ Pages of Research, Full of Highlights and Handwritten Notes Into Something Your Agents Can Use

Lindsey Boan

Leads paid media at Fulcra.

Where This Idea Came From

I found myself finally ready to revisit my Master’s capstone now that I’m a year removed from the crazy because the work still deeply mattered to me. It proposed a psychoeducational program built on an emerging approach to emotional co-regulation that draws on communities clinical research has vastly overlooked. 

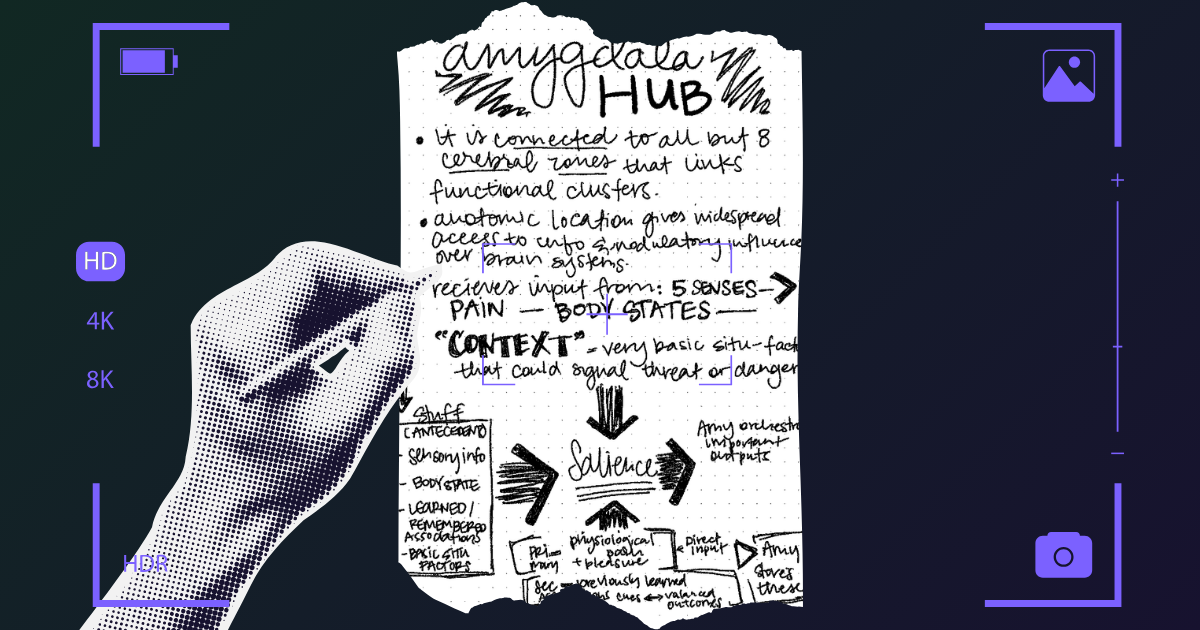
I think better on paper with a pen in my hand, and behind the final report sat 82+ peer-reviewed articles on my remarkable. Many carry my handwriting, and I highlighted, underlined, and filled every margin. I also keep completely handwritten notebooks on the tablet where I work through ethics and philosophy that doesn't belong to any single article. I had notes everywhere, across many drives and platforms. I wanted one place for all of it: the articles, my synthesis documents, my Notion notes, and my own thinking. I needed to ask it two lingering questions: What did I miss? And who else needs this?

HOW will I get 100+ files with handwritten notes and annotations on PDFs into a format I could easily use and reference? 

Problem

A reMarkable stores ink as pen strokes layered over a PDF. As is, an agent gets a picture of a page, or nothing at all.

My first plan was to export the annotated PDFs to Google Drive and let Claude read them. Handwriting turned out to be solvable, and that's its own post. Highlights fell apart. My newer documents looked unmarked to the extraction tools I tried.

My pages made it harder. I tended to mark in two ways within one document: snap-to-text highlights that lock onto printed words, and freehand swipes I draw myself. Many articles also carry dense pen underlines, boxes, and arrows.

My quest to build had its own problem. I worked through what I wanted in the skill, and trained my handwriting in Claude chat. Then I sent it to Cowork to write and run the code on my Mac. Neither session could see the other's conversation.

How to Solve

  1. Scope the input to one folder. I made a folder on my reMarkable tablet called Claude Inbox. The skill processes whatever I put there, when I ask, and leaves the rest of my library alone.
  2. Decide where outputs live. Each source gets one Google Doc in Drive. Fulcra keeps the run log and the working files every agent needs to read, which stay small.
  3. Connect to the tablet. reMarkable has no official connector. Cowork installed rmapi, an unofficial, community-maintained command-line tool. The tablet syncs itself over wifi, so a run only needs my Mac awake. I compared running it in the cloud, and the token cost came out about even, so I kept it local.
  4. Fulcra as the handoff between chat and Cowork sessions. Chat wrote a file with every design decision and the reasoning behind it. Cowork read it and wrote a response correcting the technical approach, and chat folded those corrections back in. Both sessions worked from one record instead of my memory of two conversations.
  5. Found where snapped highlights live. On current tablet software, snap-to-text highlights sit inside the page files as blocks of text, which rmscene, an open-source Python library, can read. Tools that check the older location, a separate highlights folder, find it empty. That's why my documents looked unmarked. Matching those recorded runs to the PDF word by word stalled at 91%, because superscript citation numbers fuse to the words beside them. Matching character by character placed all 243 runs in my first test article.
  6. Recovered freehand highlights from pixels. A freehand swipe leaves no text behind. The script renders the page and measures how much of each word sits under highlighter color. Measuring a stroke's outer box fails, because a curved swipe's box covers unintended words. A shape test on each marked region separates highlighter from the colored fringe around blue DOI links.
  7. Measure against my own export. The tablet's own PDF export shows my highlights exactly as I drew them, so Cowork used it as the answer key and compared word by word across six marked test pages: 4,298 words, 1,722 of them highlighted. The comparison exposed a quirk in the cloud render. It paints a sloping lead-in before each highlight, so the first Doc started my abstract highlight a sentence before I did. No threshold fixes that. Cowork tested them, and 0.08 coverage beat every higher setting.
  8. Merged the two highlight types with one rule. Where a run of highlighted pixels contains a word the tablet also recorded, it's a snapped highlight, and the tablet's boundaries win. A run the tablet never recorded is freehand, and the skill keeps it whole. Nothing I highlighted by hand gets dropped.
  9. Fixed reading order and rejoined broken highlights. Journal pages put a full-width abstract above two columns, which fooled the old column test into interleaving them. The script now finds the gutter from the whitespace itself and orders each passage by its first word. The tablet sometimes splits one highlight into pieces, at a hyphen or around a statistic in parentheses. The script rejoins gaps of one or two words, or gaps with no readable word, and removes line-break hyphens so quotes read cleanly.
  10. Added a path for handwritten notebooks. A notebook has no source PDF, so the usual render path fails. The script draws notebook pages straight from the pen strokes with rmc, another open-source tool. The first notebook came through as a transcribed Doc
  11. Shaped the output around how I read. Each Doc groups passages under the article's own section headings, quotes every highlight word for word, and sets my handwriting in italics beneath it. It adds no summaries. Stray fragments stay in, and I delete them myself.

Solution

I drop an article(s) into Claude Inbox and tell Claude to process my reMarkable inbox. The skill checks the Fulcra log for anything new or changed since the last run, so files can stay in the folder. It pulls both kinds of highlights, transcribes my pen notes, and writes one Doc per source to Drive. It does the same for my handwritten notebooks.

Fulcra holds what needs to outlast any single session: the run log, the design decisions, the calibration record, and the rules for reading my handwriting. Those files live in my account, where I control them. While I drafted this post, Cowork finished a calibration round and saved the results to Fulcra, and the chat session writing with me read them and updated the draft. Neither agent needed me to relay a thing.

Result

My first test article came through as a Doc with 41 highlighted passages across six marked pages, plus three pages of transcribed handwriting. Against my own export, the skill scored 0.988 on F1, a standard accuracy measure. False positives fell from 128 to 14, at the cost of 28 missed words out of 1,722. About fourteen short fragments per document still come through from the cloud render's lead-in, but I delete them in seconds.

I also learned a good lesson about my own habits. A snapped highlight comes straight from the tablet's record, with exact characters. So I snap whenever I can now.

Next comes the "what did I miss" pass across the full capstone corpus. Before this, my annotated articles and notebooks would have sat out of that search entirely. Now my own thinking goes in alongside the research.

Try It Yourself

You need a reMarkable with cloud sync, a Fulcra account (free to start with 5 GB), and Claude with the Fulcra connector enabled. Cowork builds and runs the scripts on your computer.

Start with four things:

  • A folder on your tablet for documents you want processed.
  • A log file in Fulcra that records what each run handled.
  • One marked-up article, plus the tablet's own export of it, so you can measure accuracy before you trust the output on volume.
  • The open-source tools this stands on: rmapi, rmscene, and rmc, each installed from its own project page.

If you’re like me and handwrite a lot, make a handwriting translation guide (link to the handwriting article? that lives in Fulcra.

Give Cowork this post and your test article, and ask it to build the same pipeline and check its output against your export.

The future is personal and private.

Fulcra was designed by people who get privacy and know the importance of an infrastructure solution that can be the secure private datastore for the rest of your life. Here data is yours, under your control, and only shared with the people and tools you choose to share it with.